How to Read a Peptide Sequence

Written by Dr. Sufia Ul Haque
Chemist and scientific writer · Published · 5 min read
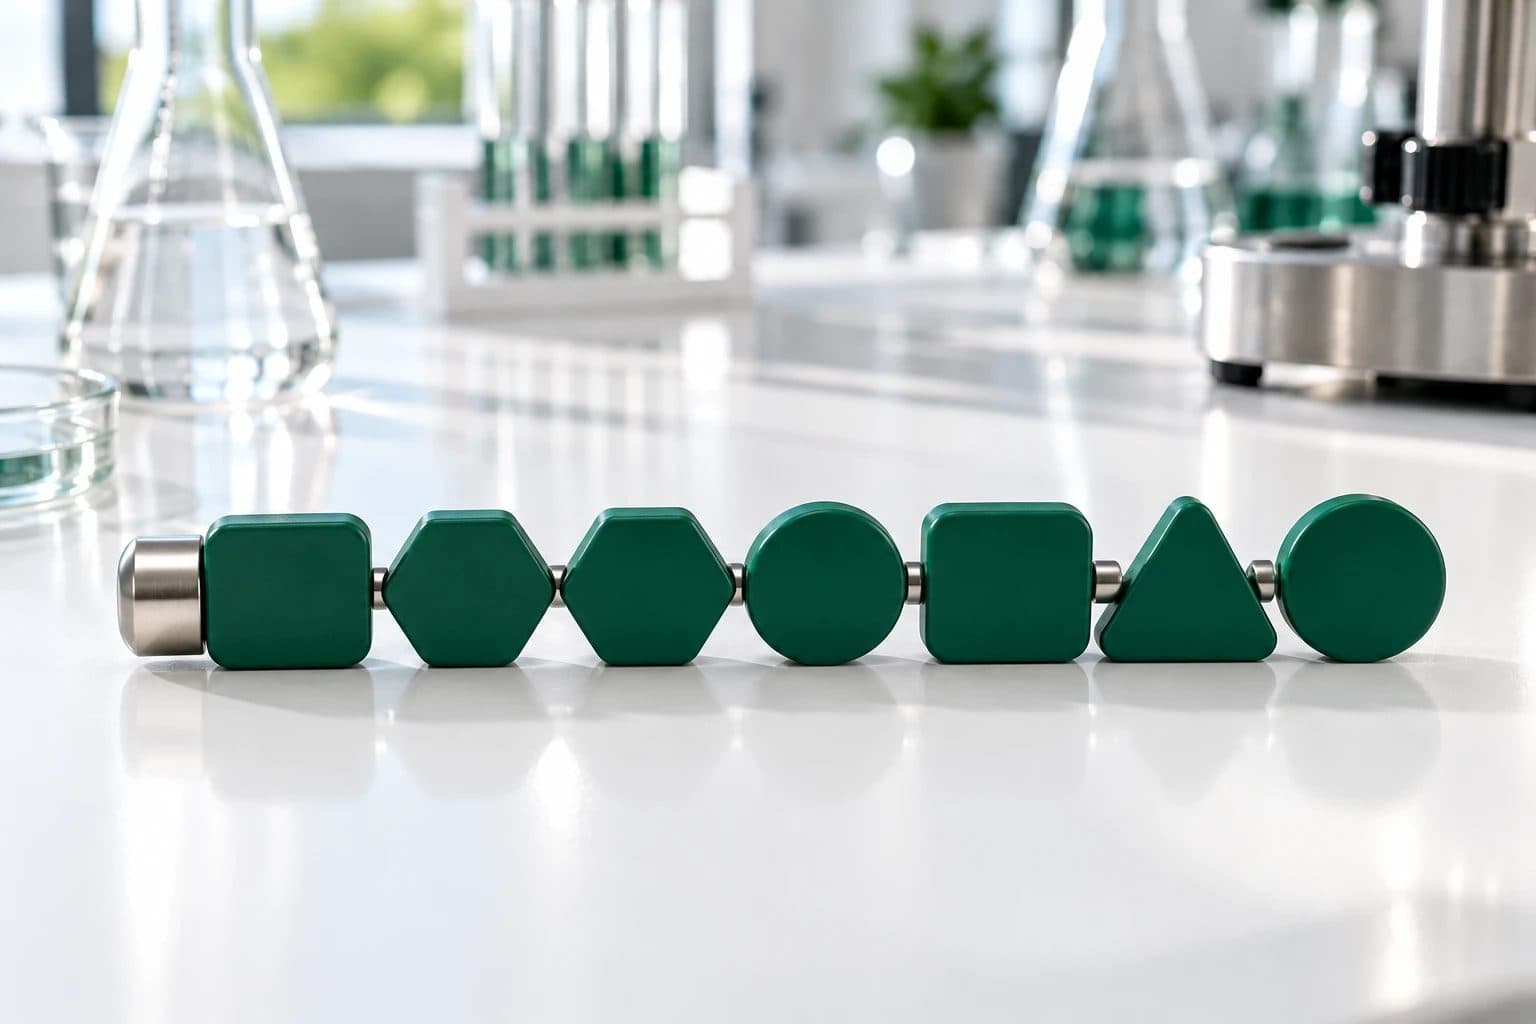
A peptide sequence shows which amino acids are joined together and in what order. It is normally read from the N-terminus on the left to the C-terminus on the right. Each amino acid has a one-letter or three-letter code. Marks such as Ac- and -NH2 describe chemical changes at the ends, not extra amino acids.
In this article+−
Which way do you read a sequence?
Read from left to right, starting at the N-terminus (amino end) and finishing at the C-terminus (carboxyl end). The International Union of Pure and Applied Chemistry (IUPAC) uses this convention and numbers residues, the amino acid units within a chain, from the N-terminal end. The ends are different because peptide bonds connect the carboxyl group of one amino acid to the amino group of the next.
RelatedWhy a chain has two different ends
A sequence is a little like a sentence: changing the order changes what it says. For example, TKPRPGP and PGPRPKT describe different peptides. The comparison has limits, though. Each letter represents an entire amino acid residue, not just a character on a page.
Count the amino acid codes to find the chain length. Do not count chemical groups written outside the sequence as residues. The order, the residue count and any modifications together help identify the molecule.
What do the codes mean?
Each of the 20 amino acids in IUPAC’s standard table has a three-letter symbol and a one-letter symbol. For example, leucine (Leu, L) and lysine (Lys, K) can be written either way. Three-letter codes usually begin with a capital followed by lowercase letters. A hyphen between three-letter residue symbols represents a peptide bond.
One-letter codes are shorter and useful when comparing long sequences. Some letters are not initials: lysine is K, tryptophan is W and glutamine is Q. IUPAC also uses X (Xaa) for an unknown or unspecified amino acid residue. The following table covers the 20 standard codes in the 1983 recommendations.
One-letterAlaThree-letterAlanineAmino acid
- AlaAlanine, one-letter code A
- ArgArginine, one-letter code R
- AsnAsparagine, one-letter code N
- AspAspartic acid, one-letter code D
- CysCysteine, one-letter code C
- GlnGlutamine, one-letter code Q
- GluGlutamic acid, one-letter code E
- GlyGlycine, one-letter code G
- HisHistidine, one-letter code H
- IleIsoleucine, one-letter code I
- LeuLeucine, one-letter code L
- LysLysine, one-letter code K
- MetMethionine, one-letter code M
- PhePhenylalanine, one-letter code F
- ProProline, one-letter code P
- SerSerine, one-letter code S
- ThrThreonine, one-letter code T
- TrpTryptophan, one-letter code W
- TyrTyrosine, one-letter code Y
- ValValine, one-letter code V
With peptides, the code system may change how a sequence looks, but it does not change the underlying amino acid order.
What do Ac-, -NH2 and -OH tell you?
These marks describe the chemical groups at the ends of a peptide. Ac- before the first residue means an acetyl group is attached to the N-terminal nitrogen. Compared with the corresponding free amino end, this adds C2H2O to the molecular formula and approximately 42.04 g/mol to the molar mass. The acetyl group is not another amino acid.
A sequence ending in -NH2 has a C-terminal amide instead of the usual carboxylic acid. Replacing the terminal -OH with -NH2 makes the molecule approximately 0.98 g/mol lighter. The symbols -OH at the end and H- at the beginning of a peptide sequence indicate free, unmodified ends. According to IUPAC, these symbols are optional, so a sequence without them is generally understood to have free ends.
The position of a chemical modification is also important. A group attached to the end of a peptide is different from one attached to an amino acid side chain. For example, Ac-LKKTETQ indicates an acetyl group at the N-terminus. This notation is commonly used with one-letter amino acid codes, although IUPAC's formal one-letter rules do not specifically address terminal modifications.
From my experience in organic synthesis, I’ve learned that even a small change in a functional group can change a molecule’s identity and properties. This is why I pay attention to terminal modifications such as Ac- and -NH2 when reading peptide sequences.
How do you read a real sequence?
Pure Peptides lists amino acid sequences in the Technical Specs section of its product pages. Two examples show how to read them.
TB-500 is written as Ac-LKKTETQ using one-letter codes. In three-letter codes, it is Ac-Leu-Lys-Lys-Thr-Glu-Thr-Gln. It contains seven amino acid residues. The Ac- indicates an acetyl group attached to the beginning of the chain. Without this group, its molecular formula is C36H66N10O13 (846.98 g/mol). With it, the formula becomes C38H68N10O14 (889.02 g/mol).
Selank is written as Thr-Lys-Pro-Arg-Pro-Gly-Pro using three-letter codes. Its one-letter sequence is TKPRPGP. It also contains seven residues. Since no end modifications are shown, both ends are normally considered unmodified.
In my work with organic compounds, checking the molecular formula and chemical structure is an important part of understanding what a compound actually is. I apply the same approach when reviewing peptide sequences, checking the amino acid order and any terminal modifications rather than relying on the name alone.
Both codes describe the same amino acid sequence. However, chemical modifications can change the molecular formula and weight.
RelatedHow to calculate molecular weight
On this site
How are D-amino acids and cyclic peptides shown?
Most amino acids in naturally occurring proteins have the L configuration. A D-amino acid is usually marked explicitly, such as D-Ala for D-alanine. Some documents use a lowercase one-letter symbol, such as a, for D-alanine, but that is not a universal IUPAC convention. Always check the notation key. Glycine has no D or L form because it is not chiral.
A peptide can also form a ring. For a ring joined through backbone peptide bonds, IUPAC permits notation such as cyclo(-Gly-Pro-Phe-). Unlike a linear peptide, this ring has no free N- or C-terminus. The order of residues still matters, but the written starting point around the ring is a convention. Other ring types, including those joined through side chains, need additional structural information.
Frequently Asked Questions
What does Ac mean in a peptide sequence?+−
Ac stands for acetyl. When written before the first amino acid code, it indicates an acetyl group on the N-terminal nitrogen. The group adds C2H2O to the formula, increasing the molar mass by about 42.04 g/mol. It is a chemical modification, not an additional amino acid residue.
What does -NH2 at the end of a peptide mean?+−
It indicates C-terminal amidation. The usual carboxyl -OH group has been replaced by -NH2, giving a different molecular formula. Compared with the corresponding free-acid peptide, the amidated form is approximately 0.98 g/mol lighter. The modification does not change the number of amino acid residues.
Why are some sequences written with one letter and others with three?+−
Both notations identify the same amino acids in the same order. One-letter symbols are compact and especially useful for long sequences or comparisons. Three-letter symbols resemble amino acid names and can be easier for newcomers to read. Neither system changes the molecule, provided the sequence and modifications are represented correctly.
Sources
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Section 3AA-1: Amino acid names. iupac.qmul.ac.uk/AminoAcid/AA1n2.html
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Sections 3AA-11 to 3AA-13: Peptide definitions, sequence direction, and residue numbering. iupac.qmul.ac.uk/AminoAcid/A1113.html
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Sections 3AA-14 to 3AA-16: Three-letter amino acid codes and peptide bond notation. iupac.qmul.ac.uk/AminoAcid/A1416.html
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Section 3AA-17: Chemical modifications. iupac.qmul.ac.uk/AminoAcid/AA17.html
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Sections 3AA-18 and 3AA-19: D-amino acids and cyclic peptides. iupac.qmul.ac.uk/AminoAcid/A1819.html
- IUPAC-IUB Joint Commission on Biochemical Nomenclature (1983). Nomenclature and Symbolism for Amino Acids and Peptides (Recommendations 1983). Sections 3AA-20 and 3AA-21: One-letter amino acid codes and sequence notation. iupac.qmul.ac.uk/AminoAcid/A2021.html
- IUPAC Commission on Isotopic Abundances and Atomic Weights (CIAAW). Abridged Standard Atomic Weights. ciaaw.org/abridged-atomic-weights.htm
Worked example
The article borrows TB-500 and Selank from the catalogue to show the idea on a real molecule.
Shop lot-tested TB-500
View Product · TB-500Shop lot-tested Selank
View Product · Selank
About the author
Dr. Sufia Ul Haque
Chemist and scientific writer · PhD in chemistry, Aligarh Muslim University
Dr. Sufia Ul Haque is a chemist and scientific writer. She holds a PhD in chemistry from Aligarh Muslim University and carried out postdoctoral research in organic and natural-product synthesis in the United States, where her work included multistep synthesis, purification and chromatography. She has published in journals including Biosensors and Bioelectronics, the Journal of Power Sources and Scientific Reports, and reviews for several international journals. She writes about chemistry for readers without a scientific background.
Disclosure: No conflicts of interest declared.
The author checked the claims in this article against its sources and approved the text as published on .